Author: Ben Walker, Marketing Director, Logicalis Group
As part of The Road to AI, Ben Walker, Marketing Director, GTM, caught up with Ulrich Vierkotter, Lead Data Center Networking Logicalis Germany and Alex Spirin, Solution Architect Logicalis Germany while the team was building the AI Pod in Cologne. A few months earlier, the project was little more than an idea. Now the infrastructure is taking shape.
They discussed what they’re building, what has already gone wrong, why AI infrastructure requires a different kind of collaboration, and what they’re learning by doing it for real.
Ben: When we last filmed you guys, none of this existed. Where are we now?
Ulrich: We’re currently working on the storage system. The servers are configured and included in the AI Pod, but storage is something we're having to work through because we haven’t used this particular system before.
With most parts of the infrastructure, we're confident. But AI introduces some additional technical requirements that you don't necessarily encounter in a normal server deployment.
GPUs are a good example. They have specific requirements around how they communicate with each other, so we need to understand those requirements and make sure the infrastructure supports them properly.
Alex: Last time, we had mounted the systems into the racks. Now we’re actually configuring everything and starting to bring it to life.
Ben: Does building AI infrastructure require different skills from a traditional infrastructure project?
Ulrich: Definitely. An AI Pod consists of several layers and you cannot have one person who knows everything.
We are infrastructure engineers, so we're focused on areas such as networking and servers. Then other specialists come in to deploy the operating system, containers and the platform. Then you have another group specialising in the AI applications themselves.
You need all of those people working together.
Alex: That's really important. We've divided the responsibilities according to who has the right expertise. Our first job is to prepare the infrastructure. Then the application developers can come in and do their part.
Ulrich: Everyone has to pull on the same rope.
Ben: The idea for this started long before the hardware arrived. Why did you want to build the lab in the first place?
Ulrich: We knew that if we wanted to get into AI properly, we needed servers with GPUs and the NVIDIA components required for things like AI inference and model training.
So we approached management and said, “Can we build a lab?”
And, of course, the first question was: “How much does it cost?”
It’s expensive.
So we had several conversations about what we could actually achieve with the lab and why we needed it.
The first reason was simple: we can learn.
We can learn how to deploy AI infrastructure ourselves.
The second was that we could use it to show customers what an AI deployment could look like within their own on-premises environment.
Ben: Why is proving that important for customers?
Ulrich: Because most customers are still at the beginning of their AI journey.
They're asking: How should I start? Should I go to the cloud? Should I create something on-premises? What infrastructure do I actually need?
And AI is always about data.
That data can be extremely sensitive, so some customers may not want their applications or data running in the cloud. They start thinking about an on-premises environment, but then another question appears:
How do I actually build it?
Our goal is to be able to show customers how they can run sensitive AI applications on their own infrastructure in a way that is performant and secure.
Alex: And once we have real applications running, we can also start comparing the options. Not only technically, but financially.
We can look at the costs of an on-premises solution and compare those with consuming AI services from the cloud.
Ben: We’re showing the real journey with this project, not just the successes. What has gone wrong so far?
Ulrich: We had some challenges getting the initial server management running, and then we ran into issues when we started building the OpenShift cluster.
We would add the servers into the environment as workers and encounter an error. We'd look through the logs, understand the fault, change something and run the discovery again.
Then we'd find the next problem.
So we went through several rounds before we really got everything running.
Alex: In the documentation, everything works on the first attempt. In reality, you need some effort to get it working.
That is part of what we're learning.
Ben: Was there ever a point where you thought: we've taken on too much here?
Ulrich: No. We were always confident that we'd get it running.
Alex: Because we have the people around us.
We have a team made up of experts from multiple parts of the business. If our own knowledge isn't enough, we can immediately ask somebody who has that expertise.
That has been really important.
Sometimes we deliberately get everyone into the same room. If one system isn't reachable, for example, instead of creating a ticket or organising another call, I can just turn to someone and ask them to check it.
Especially at the beginning, that makes everything much faster.
Ben: Can you give me an example of something you discovered by actually building the environment?
Ulrich: We found a good example involving the GPUs.
For demanding AI applications, you might need to distribute a workload across several GPUs. To do that efficiently, those GPUs need to communicate with each other, and the network has to support some very specific requirements.
We discovered that the switches we'd originally bought didn't support one of the features we needed.
That's the type of thing that can go wrong. You can buy something and then discover it doesn't completely support what you need.
Fortunately, we found a workaround and have other switches that can support it.
But these are exactly the things you learn when you build the environment for yourself.
Ben: You've both volunteered to work on this project alongside your normal customer work. Why?
Alex: Because we need to be part of this change.
There are unexpected and unknown things because the technology is so new. That's exactly why it's important for us to start working with it now, rather than waiting until later.
Ulrich: I've always been interested in new technology.
As infrastructure engineers, we're not developing the AI models ourselves. Our challenge is different: how do we create the infrastructure that supports what AI workloads need today?
That's what makes this interesting.
I've worked with technology for more than 20 years, and there have been many innovations during that time.
AI is one of the most interesting.
Learning by doing
Perhaps the biggest lesson from the conversation wasn't about GPUs, switches or OpenShift. It was the importance of experience. The team doesn't expect every decision to be right first time. They're building, testing, finding problems, bringing in different expertise and trying again. And that's precisely why the AI Pod exists.
Because before we can confidently help customers navigate their own road to AI, we need to travel it ourselves. That journey is still very much underway.
The Road to AI: a Logicalis docuseries
Catch up with episode 1: The idea
Catch up with episode 2: The build
Related Insights
Global , Nov 10, 2026
Road to AI, Episode 2: When the blueprint meets reality
In Episode 2 of Road to AI, we follow the Logicalis team as the technology comes together, real-world challenges emerge, and attention turns to the use cases that will put the platform to the test.
Global , Nov 5, 2026
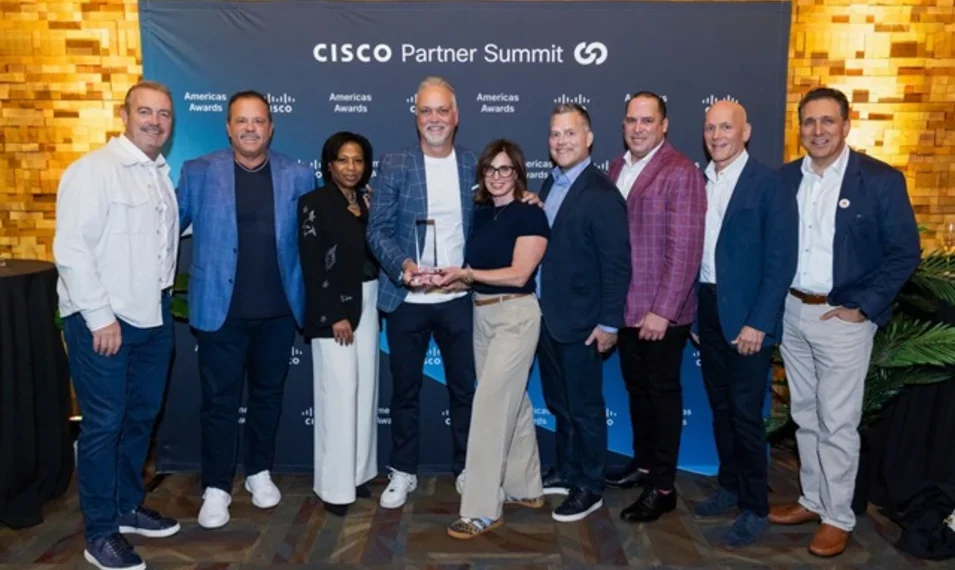
Logicalis celebrate 10 award wins at Cisco Partner Summit 2026
Logicalis celebrates 10 wins at Cisco Partner Summit 2026, recognising its global expertise across managed services, security, collaboration and infrastructure.
Global , Oct 30, 2026
Press Release
Logicalis strengthens global managed services with Cisco Secure Networking Specialisation
Read how Logicalis has become the first Cisco global partner to achieve the Secure Networking Specialisation across five countries, strengthening its ability to deliver secure, resilient and AI-ready managed services globally.
Global , Oct 22, 2026
Cyber security's new reality: Every organisation is now on the front line
Logicalis CEO Bob Bailkoski shares his thoughts on cyber-security's new reality and how it is impacting organisations across the globe.
Global , Oct 20, 2026
Circularity in IT: The overlooked strategy for operational performance
Circularity in IT is as much an operational strategy as it is a sustainable one. It is about getting more value from the technology you already own, reducing dependency on finite resources, and making smarter decisions throughout the entire lifecycle of your IT estate.
Global , Oct 8, 2026
Announcement, Press Release
Logicalis recognised as Canalys Forum EMEA Partner of the Year
The award recognises Logicalis’ growth, expanding managed security capabilities and continued sustainability momentum across EMEA.
Global , Oct 1, 2026
Announcement
Webinar: What organisations with mature security do differently: 5 lessons from a global SOC
What do mature security organisations do differently? Join two Logicalis global SOC leaders as they reveal five practical actions to improve cyber readiness, strengthen resilience, and reduce risk.
Global , Oct 1, 2026
Announcement, Press Release
Nearly two-thirds of organisations lack mature 24/7 security operations, Logicalis research finds
New global benchmark reveals a widening gap between cyber security investment and operational readiness as AI accelerates the speed of attack and defence.
Global , Aug 28, 2026
The questions I’m hearing from security leaders across APAC
In the post-Mythos era, AI-powered SOCs are helping organisations improve cyber resilience by automating threat detection, prioritising exploitable vulnerabilities, and enabling faster incident response.
Global , Aug 24, 2026
Copilot in action: How Logicalis is turning AI into advantage
Read how Logicalis is turning Microsoft 365 Copilot adoption into measurable business value, achieving 11:1 ROI and 96% user adoption while creating a scalable blueprint for AI-powered transformation.
Global , Aug 7, 2026
The top global AI leadership challenges
Logicalis CEO, Bob Bailkoski, explores the key AI leadership challenges facing CIOs today, highlighting the need to balance rapid AI adoption with strong governance, scalable foundations and trusted ecosystems to deliver lasting business value.
Global , Jul 30, 2026
The AI opportunity: are we creating a better future of work?
As artificial intelligence moves from experimentation into everyday business reality, organisations face a defining question: are we using AI simply to do more, or to create better work?
Global , Jul 29, 2026
The attack before the attack: Why organisations need earlier visibility into cyber risk
The next evolution of cybersecurity is not responding faster, but seeing threats sooner. See how Cyber Threat Intelligence helps organisations move from reactive defence to proactive risk management by uncovering threats before they reach the network.
Global , Jul 16, 2026
How to scale AI without scaling your carbon footprint
Artificial intelligence has rapidly moved from experimentation to execution. But as AI adoption accelerates, a crucial question is emerging in boardrooms around the world: how do you scale AI without scaling energy consumption, operational costs and carbon emissions?
Global , Jul 14, 2026
Harnessing AI in the Manufacturing Industry
Manufacturers are rapidly accelerating AI adoption to improve efficiency, decision-making, and innovation, but achieving scalable, secure, and sustainable outcomes requires stronger governance, operational readiness, and risk management.
Global , Jul 14, 2026
Harnessing AI in the Financial Services Industry
AI is rapidly reshaping financial services, creating significant opportunities for innovation, efficiency, and customer experience, but organisations must overcome challenges around scale, governance, security, and trust to realise its full value.
Global , Jul 14, 2026
Harnessing AI in the Energy Sector
AI is rapidly transforming the energy sector, but while organisations are increasing investment to drive efficiency, sustainability, and growth, many face significant challenges in scaling AI securely, responsibly, and effectively across the business.
Global , Jul 1, 2026
Press Release
Logicalis achieves Microsoft Frontier Partner status to accelerate enterprise AI adoption
New Microsoft Frontier Partner status and Copilot specialisation strengthen Logicalis' ability to help organisations move from AI experimentation to secure, governed enterprise-scale adoption
Global , Jul 1, 2026
What is Microsoft Frontier Partner status?
Discover how Logicalis’ global Microsoft Frontier Partner recognition empowers you to accelerate scalable, enterprise-wide AI transformation with proven results.
Global , Jul 1, 2026
Logicalis leaps into enterprise AI with Frontier Partner status and Copilot specialisation
Read how Logicalis’ Microsoft Frontier Partner status and 12 Advanced Specialisations helps securely scale AI and turn ambition into measurable business impact.
Global , Jun 22, 2026
What’s on my mind in cybersecurity right now
As a cybersecurity professional with more than 25 years’ experience, I have always known security to be fast-moving. But the pace of change being driven by AI feels different. This is not just another evolution in technology; it is a fundamental shift in how threats emerge, how quickly they scale and how organisations need to respond.
Global , Jun 4, 2026
The AI Scaling gap: why ambition is outpacing readiness
Organisational AI appetite has reached fever pitch. However, beneath this surge of ambition lies a growing disconnect: while the will to innovate is clear, the roadmap for execution is not.
Global , Jun 3, 2026
From infrastructure to orchestration: navigating the current AI risk
In the rapid evolution of the digital enterprise, 2026 has become the year where the promise of AI met the reality of the cyber frontline. For many IT leaders, the initial excitement surrounding AI has been replaced by a sobering realisation that the technology is maturing faster than our ability to secure it.
Global , Jun 1, 2026
Penetration testing in 2026: 10 shifts security leaders need to know
Read why penetration testing is evolving from a periodic, report-led exercise into a continuous, platform-driven capability that provides real-time visibility, risk-based prioritisation, and ongoing remediation to reduce cyber exposure.
Global , Jun 1, 2026
Penetration testing isn’t the end goal. Proactively reducing exposure is.
Read how modern CISOs are shifting penetration testing from a one‑off audit exercise to a continuous, risk‑driven vulnerability management process that ensures issues are prioritised, fixed, and proven closed.
Global , May 27, 2026
AI without security is a business liability
AI is rapidly becoming the defining technology of our time. Across every industry, organisations are experimenting, piloting and scaling AI to drive productivity, accelerate insights and unlock new value. But there is a growing risk that cannot be ignored: deploying AI without the right security foundations turns innovation into exposure.
Global , May 27, 2026
Circularity beyond recycling
For many organisations, circularity starts and stops with recycling. It’s visible, easy to measure, and widely understood. But focusing only on what happens at the end of an asset’s life means missing the biggest opportunity: keeping technology in use for longer.
Global , May 18, 2026
Announcement
Securing Agentic AI: Why data governance is the new perimeter
CIOs are being asked to scale AI quickly—without losing control of security, compliance, or cost. As AI moves from “answering questions” to acting through agents, the goal is to let it move fast inside clear guardrails. That’s where data governance comes in: it’s the control plane that decides what an agent can see, what it can do, and what it can change.
Global , Apr 24, 2026
Data in motion, security by design: Architecting for the intelligence era
The Intelligence Era demands more than isolated technology decisions. Read how Logicalis and Cisco help organisations build the right ecosystem to scale AI securely, transforming complex infrastructure into a platform for growth.
Global , Apr 20, 2026
Has AI reduced the human risk in Cybersecurity, or multiplied It?
As AI‑enabled attacks exploit trust and human decision‑making, security leaders face a new challenge: protecting people, not just technology. Phil Tobolski explores how organisations can adapt security models to keep pace with AI‑driven deception.
Global , Apr 10, 2026
CIOs leading the charge into an AI powered future
AI continues to be the hottest topic in boardrooms and IT departments across the globe. The 12th annual Logicalis Global CIO Report, reveals a widening gap between ambition and operational readiness, with governance, skills and infrastructure struggling to keep pace.
Global , Apr 8, 2026
Press Release
Securing AI becomes top priority as CIOs rank AI alongside malware, ransomware and phishing as major cyber risk
Securing AI has become a top priority for CIOs, with over a quarter reporting AI as a significant source of risk, according to the Logicalis Global CIO Report 2026.
Global , Mar 27, 2026
Why the cybersecurity skills gap is growing - and how managed SOC and XDR can close it
With internal security teams increasingly overstretched, organisations are feeling the impact of the growing cyber skills gap every day. In our latest webinar experts shared how managed SOC and XDR services help shift the burden, delivering stronger protection without adding complexity.
Global , Mar 25, 2026
Why sustainability is becoming one of the most powerful drivers of profitability
Sustainability has become one of the most powerful levers for profitability, resilience, and long-term organisational value. Senior leaders who recognise this shift are positioning their businesses to outperform competitors, attract stronger talent, and meet the rising expectations of customers, regulators, and investors.
Global , Mar 25, 2026
Announcement, Press Release
Logicalis Germany acquires NetworkedAssets, establishing a presence in Poland
Strategic acquisition expands software development, network automation and observability capabilities, with Berlin presence and a strong engineering base in Poland
Global , Mar 2, 2026
Press Release
Logicalis 2026 CIO Report: CIOs navigate surging AI investment amidst growing governance concerns
Organisations are racing to invest in AI faster than they can manage it. According to the Logicalis CIO Report, which surveys over 1,000 CIOs globally, a gap is emerging between ambition and operational readiness, with governance, skills and infrastructure struggling to keep pace.
Global , Feb 19, 2026
Our Communities: Building brighter futures together
At Logicalis, our commitment to responsible business goes far beyond our own walls. We believe that true success means making a positive difference in the communities where we live and work. That’s why our social and community development goals are focused on improving education, supporting local charities, and empowering the next generation, especially in Science, Technology, Engineering, and Mathematics (STEM).
Global , Feb 16, 2026
Why humans are still the weakest link in your organisation's cyber defence
Attackers don’t break in: they log in. Our latest global research from IDC reveals why human identities are the weakest link behind every major ransomware entry point.
Global , Feb 12, 2026
Announcement
Our People: Belong, Grow and Thrive
We know that when individuals from diverse backgrounds come together, innovation flourishes and real value is created – not just for our business, but for the technology sector and the wider world. That’s why we’re committed to building an environment where everyone can belong, grow and thrive.
Global , Feb 11, 2026
Q&A with Mike Fry: Tackling the Cybersecurity Skills Gap
To accompany the release of the recent IDC infographic “From Shortage to Strength: Fixing the Cyber Skills Gap,” we sat down with Mike Fry, to get his insights and what they mean for organisations today.
Global , Feb 4, 2026
Is cybersecurity burnout our biggest looming threat?
As Logicalis launch their latest Cybersecurity Newsletter on LinkedIn, Mike Fry explores why alert fatigue, complexity and human‑centred risks may be today’s biggest threat to resilience.
Global , Jan 12, 2026
From shortage to strength: Fixing the cyber skills gap
Discover why the cybersecurity skills gap is putting businesses at risk and how managed security services can bridge the shortage. Learn strategies to boost resilience, reduce costs, and stay ahead of AI-driven threats.
Global , Dec 10, 2025
Announcement
AI and digital transformation: COP30 signalled a new era for climate action
COP30 in Belém, Brazil marked a turning point for climate action, elevating technology and AI as key drivers of sustainability. Discover how digital innovation, from emissions tracking to AI-powered resilience, is shaping the future of climate strategy and operational excellence.
Global , Dec 8, 2025
What COP30 means for digital transformation and sustainability
COP30 was held in Brazil this year, with much attention focused on adaptation finance and forest protection but for the first time we saw the rise of technology and AI on the agenda.
Global , Dec 4, 2025
Threat Hunters: The front-line defenders in a modern SOC
“Threat hunting isn’t just about locating adversaries; it’s about anticipating their moves, proactively searching for hidden risks, and transforming intelligence into action before a breach occurs, says Gandhiraj Rajappan, SOC Manager at Logicalis Asia Pacific.
Global , Dec 4, 2025
Logicalis Spain awarded Rising Star Consulting Partner of the Year 2025 by AWS
The AWS Regional Partner Awards celebrate top partners in each region who stand out for their specialisation, innovation, and collaboration. Read why Spain achieved this award.
Global , Nov 21, 2025
Announcement
Logicalis achieves Cisco Managed Firewall and SSE Cisco Powered Service designations, enhancing managed security offerings for customers
Logicalis is a leader in achieving strategic Cisco Powered Services (CPS) designations worldwide, with a focus in managed network and managed security services.

Global , Nov 19, 2025
Why APAC is the prime target for cybercriminals
The Asia-Pacific region has become a global hotspot for cybercrime, accounting for 34% of incidents in 2024. As a critical component of the global supply chain and its position as a technology and manufacturing hub, the region is an irresistible target for cybercriminals.
Global , Nov 18, 2025
Logicalis Spain, recognised as FinOps Partner of the Year at the IBM Ecosystem Summit 2025
Logicalis Spain is thrilled to receive this award at the IBM Ecosystem Summit, which recognises its leadership in cloud financial optimisation and multi-cloud management.
Global , Nov 13, 2025
Announcement
Logicalis recognised with 15 awards at the Cisco Partner Summit 2025
With a range of 17 Cisco global powered solutions, Logicalis is proud to have been recognised with 15 awards across all regions at the Cisco Partner Summit 2025. This annual event brings together partners for a range of keynote presentations, strategic discussions, innovation sessions, and more.

Global , Oct 30, 2025
The power of Responsible Business
Customers, partners, investors, and employees are all looking for organisations that not only deliver results but do so with integrity, transparency, and a genuine commitment to making a positive impact. This is where a Responsible Business department comes in – and why its role is more critical than ever.
Global , Oct 30, 2025
Press Release
Logicalis invests in and expands Intelligent Security solutions to combat escalating cyber threats
With cyber threats reaching critical levels worldwide, 88% of organisations experienced a cybersecurity incident in the last 12 months, and 43% faced multiple breaches. In response, Logicalis announces strategic investment and an expanded portfolio of Intelligent Security solutions, designed to give organisations proactive protection, continuous visibility, and regulatory confidence in an increasingly complex threat landscape.
Global , Oct 29, 2025
Press Release
Logicalis achieves major sustainability milestones and expands global community impact
A strong focus on people, planet and communities has driven several notable achievements, including carbon neutrality for Scope 1 and 2 emissions, more women in leadership positions and more under-represented groups reached through community STEM education programmes.
Global , Sep 25, 2025
Pushing the boundaries - why diversity is the key to tech's future
The technology sector shapes the world we live in and the future we imagine. VP of Global Alliances, Anita Swann, shares her perspective on the boundaries that the tech industry still has to break and how it can be done.
Global , Sep 24, 2025
Logicalis CEO walking the walk with Sustainability
Logicalis CEO Bob Bailkoski is leading by example on sustainability, helping customers cut carbon and energy costs while driving internal carbon neutrality and community impact.
Global , Jul 29, 2025
The Data Dilemma of Sustainability: Why Measuring Impact Isn’t Just a Numbers Game
Explore how Logicalis tackles sustainability data challenges using IBM Envizi, blending ESG metrics with qualitative insights for meaningful impact.
Global , Jul 22, 2025
In the news, Blog
Simplifying Cybersecurity: A Strategic Imperative for the Digital Age
As cyber threats grow, organisations add more tools—yet this complexity itself has become a major security risk. Artur Martins, CISO Logicalis, highlights how CIOs can develop simpler, modern security strategies
Global , Jul 22, 2025
In the news, Blog
Untangling complex cybersecurity stacks in a supercharged risk environment
Artur Martins, Logicalis CISO discusses the growing complexity of cybersecurity stacks in the face of escalating cyber threats.
Global , Jul 22, 2025
In the news, Blog
The Engine for Business Growth: Embracing Innovation and Technology
Logicalis CEO, Bob Bailkoski unpacks the key insights from this year’s CIO Report, offering actionable strategies for success.
Global , Jul 7, 2025
Balancing AI growth with carbon reduction goals
Artificial intelligence has moved from the fringes of operational considerations to the forefront of operations. As organisations race to implement AI innovations, we all face a critical question, how do we reconcile the energy-intensive nature of AI with existing sustainability commitments?
Global , Jun 26, 2025
Press Release
Logicalis reaches carbon-neutral milestone on its journey to Net Zero
Logicalis announces it has achieved its 2025 target for carbon neutrality in Scope 1 and 2 emissions - marking a significant milestone in the company’s journey to reach its SBTi-validated goals.
Global , Jun 25, 2025
Blog, Videos
Logicalis reaches carbon neutrality: Scope 1 & 2 emissions milestone achieved
Watch as Bob Bailkoski discusses how Logicalis has achieved carbon neutrality for its Scope One and Scope Two emissions, reaching its 2025 target.
Global , Jun 19, 2025
From carbon neutral to net-zero: Why milestones matter on the road to sustainability
At Logicalis sustainability isn’t a secondary activity. It’s embedded in our DNA. As we mark our achievement of carbon neutrality for Scope 1 and 2 emissions, it’s a moment to reflect on not only how far we’ve come, but also on the road ahead.
Global , Jun 12, 2025
Inside the World of Managed Security Services: An Interview with James Hampson
To uncover the inner workings of cybersecurity and the services offered by Logicalis, we spoke with James Hampson, Managed Security Services Director. His insights into the Security Operations Center (SOC) reveal the complexities, challenges, and triumphs of safeguarding customer environments.
Global , May 29, 2025
Why circular IT is a strategic imperative for CIOs in 2025
The convergence of sustainability and profitability is reshaping how CIOs approach technology strategy. Circular IT is no longer just a green initiative – it’s a strategic imperative. By extending the lifecycle of IT assets, reducing e-waste, and leveraging vendor takeback programs, CIOs can transform their departments into sustainability powerhouses while unlocking new economic value.
Global , May 27, 2025
Blog, Videos
Logicalis celebrates World Cultural Diversity Day
In celebration of World Cultural Diversity Day, we’re honouring the unique stories and perspectives that strengthen our team. When diverse voices unite, creativity thrives and innovation follows. Watch now ...
Global , May 27, 2025
Logicalis becomes the first global Cisco partner to launch XDR as a Service
Read this great article by Pedro Morgado as he discusses how the strategic partnership with Cisco helps Logicalis strengthen its cybersecurity leadership with the global launch of Cisco XDR.
Global , May 27, 2025
The Value of Human Teams in a SOC: Enhancing Security Operations
Why technology alone isn't enough to safeguard your organisation - the importance of the human element in a security operations centre (SOC) and why it can't be underestimated. Article by Artur Martins, CSIO Logicalis Portugal.
Global , May 22, 2025
Press Release
Logicalis launches Managed Secure Firewall and SSE solutions to enhance customer connectivity
Logicalis adds Managed Secure Firewall and SSE to its Intelligent Connectivity portfolio, helping customers secure and scale their networks in today’s digital world.
Global , May 22, 2025
Press Release
Logicalis becomes first Cisco XDR CPS Specialisation Partner to offer global Cisco MXDR
Logicalis is the first Cisco XDR CPS Specialisation Partner to deliver Cisco MXDR as a global managed service, enhancing 24/7 threat detection and response.
Global , May 20, 2025
Tackling the tech gender gap
The gender gap in tech remains a persistent issue and without action, disparities in representation and pay will continue. Dina Knight joins HR Grapevine's podcast to discuss how Logicalis is committed to change—challenging bias and building an inclusive, empowering environment for women in tech.
Global , May 16, 2025
How Managed XDR provides CIOs with confidence in their Cybersecurity coverage
Roger Loh, Head of Global Solutions, Logicalis, explores how Managed Extended Detection and Response (MXDR) equips CIOs with the visibility, control, and expert support needed to strengthen cybersecurity posture and reduce risk across the enterprise.
Global , May 13, 2025
AI that works for you in the age of watsonx
IBM’s watsonx platform helps organisations strike the right balance between building custom solutions and adopting ready-made AI to drive real value. Scott Hodges explores the platform’s capabilities and uncovers how it can accelerate innovation across your business.
Global , May 13, 2025
From Smart Factories to Smart Ports: The Rise of Private 5G
Private 5G is redefining enterprise connectivity. While initial costs may be higher than Wi-Fi, the long-term gains in automation, efficiency, and ROI make it a smart investment for future-ready businesses.
Global , Apr 29, 2025
Blog, Videos
Shaping the future women in tech
Logicalis' VP of Global Alliances, Anita Swann, shares her perspectives on the future of tech and the importance of encouraging more people to enter the industry.
Global , Apr 29, 2025
Leadership: A journey of learning and responsibility
Leadership is often perceived as guiding a team toward success, making critical decisions, and ensuring smooth operations. However, in my experience, leadership is much more than that. It’s about learning, adapting, and taking responsibility—not just for yourself but for the team as a whole.
Global , Apr 24, 2025
Driving Sustainability Forward: The Power of Innovative Partnerships
Sustainability is a journey requiring continuous innovation and collaboration. In this article, Cisco discusses how its partners, including Logicalis, drive meaningful change with unique solutions to support business needs and sustainability goals.
Global , Apr 23, 2025
The triple bottom line: People, planet and profit
Leading the charge in sustainability not only benefits the planet but also affects people and profits, aligning with the concept of the triple bottom line. This mindset is not exclusive to IT; anyone, from plumbers to software developers, can adopt a more sustainable mindset to minimise environmental impact.
Global , Apr 23, 2025
Shaping a more inclusive future
Technology is a cornerstone of the modern world, yet the industry remains dominated by men, with women only making up a fraction of overall leadership positions. The question is, how can technology truly serve everyone if half the population it serves are underrepresented in shaping its future?
Global , Apr 10, 2025
Developing pragmatic and profitable partnerships
Technology partnerships are essential in this evolving landscape. While many CIOs believe vendors understand their business needs, 59% find vendor solutions are too complex to manage effectively.
Global , Apr 10, 2025
Avoiding the security spending black hole
The Logicalis Global CIO Report 2025 uncovers a paradox that increased spending has not reduced the frequency of security breaches.
Global , Apr 10, 2025
Innovation with intent: The CIO's mandate to unlock growth through technology
Emerging technologies such as AI, machine learning and IoT are becoming central to business transformation. The Logicalis CIO Report 2025 reveals a growing emphasis on demonstrating tangible business impact.
Global , Apr 9, 2025
ESG meets ROI: Technology's dual dividend
The increasing intersection of environmental sustainability and business performance has led to 91% of organisations surveyd in the Logicalis CIO Report 2025 reporting that they have experienced financial benefits form adopting environmental technologies.
Global , Mar 17, 2025
Blog, Videos
Celebrating International Women's Day 2025
To celebrate IWD 2025, we hosted a webinar with senior leaders across Logicalis to discuss rights, equality and empowerment for women.
Global , Mar 17, 2025
Press Release
Logicalis 2025 CIO Report: CIOs under pressure to deliver a return on innovation
Logicalis has released its annual CIO Report, which reveals that 95% of organisations are actively investing in technology to create new revenue streams within the next 12 months. Read more key findings from this year's annual survey.

Global , Feb 7, 2025
Introducing Logicalis’ Interim Responsible Business Leader
Logicalis has a new Interim Responsible Business leader, Nick Zinzan. Read this Q&A session to understand more about his background and his key focus for Logicalis' key sustainability goals for 2025.
Global , Jan 14, 2025
Architecting change: Gender bias and broader DEI challenges
In this article, Dina Knight, CPO Logicalis shares her personal and professional experience with gender bias, wider DEI industry challenges, and practical examples of how to architect change towards true inclusivity.
Global , Dec 6, 2024
International Workforces: the balance of global policies and local relevance
Speaking to HR World, our CPO Dina Knight shares valuable insights about successfully managing and nurturing diverse multicultural workforces.
Global , Nov 28, 2024
Future Face of Tech Leadership: Mastering the ‘Trifecta of Disruption’
"Disruption is redefining tech leadership, with regulation emerging as a critical new force," according to Logicalis CEO Robert Bailkoski.
Global , Nov 11, 2024
Logicalis becomes the first global partner to launch Cisco XDR
Watch as Cisco's VP of Product Management for Threat Detection and Response, AJ Shipley, and Logicalis' CTO, Toby Alcock, discuss the significance of Logicalis being the inaugural partner to introduce Cisco (XDR) as a Managed Service (MXDR)
Global , Nov 8, 2024
Press Release
Logicalis becomes the first global partner to launch Cisco XDR as a managed service
Logicalis has become the first global Cisco partner to launch Cisco Extended Detection and Response (XDR) as a Managed Service (MXDR).
Global , Nov 5, 2024
In the news, Blog
Logicalis renews Microsoft Global Azure Expert MSP status
Logicalis are proud to announce they have renewed the prestigious Global Azure Expert Managed Service Provider (AEMSP) certification, validating the highest possible standard of managed cloud services.
Global , Oct 24, 2024
Press Release
Logicalis recognised as Global Sustainability Partner of the Year 2024
Logicalis receives the global accolade, in recognition of its leadership and performance in sustainable practices for the second year running
Global , Oct 14, 2024
Press Release
Logicalis launch Sustainable IT solutions blueprint to accelerate their customers journey to net zero
Logicalis announced the launch of its comprehensive Sustainable IT solutions blueprint, designed to propel organisations towards a more environmentally conscious and carbon efficient IT infrastructure.
Global , Sep 30, 2024
Interview series - Part 2: APAC CEO Chong-Win Lee shares regional trends from the 2024 Logicalis CIO Report
Antoinette Georgopoulos, Content and Communications Manager at Logicalis Australia, continues her interview with Chong-Win Lee (Win), CEO of Logicalis Asia Pacific.
Global , Sep 25, 2024
Press Release
Logicalis win prestigious TSIA Star award
Logicalis announced as winners of the TSIA Star Award 2024 for Innovative KPIs in Managed Services. This accolade underscores our commitment to delivering cutting-edge Managed Services that empower CIOs along the value chain in their digital transformation journey.
Global , Sep 11, 2024
Press Release
Logicalis announces significant progress towards sustainability targets
Logicalis is proud to share our inaugural Responsible Business report for FY24 which sets out our ambitions, progress and future plans related to our responsibility agenda for our people, our communities and our planet.
Global , Aug 28, 2024
Blog
Circular logic: Why IT leaders need to embrace circularity for sustainable IT
Discover how embracing Circular IT can transform your IT department into a sustainability powerhouse. This article explores the top 5 ways IT leaders can deliver on sustainability goals.
Global , Aug 8, 2024
Blog
Logicalis scales to new heights with Microsoft in FY24
With awards season behind us and an outstanding year of growth, customer outcomes and new capabilities, Logicalis, has received significant recognition for our outstanding partnership with Microsoft in FY24.
Global , Aug 6, 2024
In the news, Blog
Tech polluting as much as airlines. Why crystal-clear ambition is needed
CIOs are no longer peering into the sustainability debate from the outskirts. They are at the centre of it, driving conversations and influencing future decision-making.
Global , Jul 31, 2024
In the news, Blog
Women in tech: Finding an employer that will support career growth
Dina Knight, CPO at Logicalis shares her insights on what women should look out for when considering organisations that will support their career growth.
Global , Jul 31, 2024
Blog
How can C-level leaders unlock enterprise value through Sustainability?
Read how CEOs and other top executives can champion sustainable practices, to inspire the entire company to prioritise responsibility and innovation. Join our LinkedIn live - Increasing Enterprise Value through Sustainability - on Wednesday 11th September 2024.
Global , Jul 31, 2024
APAC CEO Chong-Win Lee shares regional trends from the 2024 Logicalis CIO Report
Antoinette Georgopoulos, Content and Communications Manager at Logicalis Australia, caught up with Win to discuss his thoughts on the Asia Pacific trends and results from the Logicalis Global CIO Report for 2024.
Global , Jul 22, 2024
In the news
AI: Security risk versus business reward in a hybrid working world
Protect your organisation from cyber threats with AI powered security solutions. Enable flexible working while ensuring data privacy and protection. Read Bob Bailkoski's article originally published in Forbes.
Global , Jul 1, 2024
Press Release
Logicalis 2024 CIO Report: Sustainability a top focus for tech investment
Discover how tech leaders are prioritising sustainability and investing in initiatives and technologies to achieve environmental objectives. Find out why IT plays a crucial role in achieving sustainability goals.
Global , Jun 14, 2024
Unlocking the future of mining: Logicalis at the Future of Mining Perth 2024
We’re thrilled to announce that Logicalis Australia will be attending the Future of Mining Conference 2024 in Perth for the very first time!
Global , May 30, 2024
How Logicalis is strengthening cybersecurity for a secure future
Discover how Logicalis' Intelligent Security solution leverages advanced technologies and proactive strategies to provide comprehensive threat protection, detection, and response capabilities for your business. Stay ahead of the ever-growing cybersecurity threat landscape.
Global , May 30, 2024
Good AI. Bad AI.
Discover how AI-driven security solutions analyse network activity, detect anomalies, and predict potential exploits. Protect your business from emerging threats with our advanced AI technology.

Global , May 30, 2024
Optimising secure connectivity for IoT with Logicalis Managed Services, powered by Cisco
Read our latest whitepaper, to help improve productivity, scalability, and security with Logicalis Intelligent Security's Secure Connectivity solution. Powered by Cisco, it supports a wide range of use cases, including 5G and IoT, for enhanced productivity and data security.
Global , May 30, 2024
Join Us at EXPONOR: Unlocking the Future of Mining
As part of our Logicalis Mining World Tour, we are thrilled to announce our participation at EXPONOR, an exhibition held in Antofagasta, Chile, to assist our mining customers in solving their most complex challenges.
Global , May 7, 2024
Press Release
Logicalis enhances global security services with the launch of Intelligent Security
Logicalis announces the launch of Intelligent Security, a blueprint approach to its global security portfolio designed to deliver proactive advanced security for customers worldwide
Global , May 7, 2024
Press Release
Logicalis unites Australia and Asia operations as Logicalis Asia Pacific
Logicalis announces the creation of a new Asia Pacific entity, combining its Logicalis Australia and Logicalis Asia operations.
Global , May 7, 2024
My life building bridges (and opportunities) in tech
Anita Swann, Group Alliance Director, Logicalis offers her advice as to what do we need to grow the tech industry of the past into the tech industry of the future.
Global , Apr 17, 2024
Press Release
Logicalis net-zero emissions targets approved by Science Based Targets initiative (SBTi)
Logicalis joins the global movement towards corporate net-zero with validated and approved science-based targets, aligning with the Paris Agreement goals.
Global , Apr 12, 2024
A decade of insight reveals the future of tech leadership in the Logicalis Global CIO Report 2024
It’s been ten years since the Logicalis CIO report was launched. It was designed as a pulse check on the mood in the industry, to identify common CIO challenges and ambitions and to serve as a reminder that we are part of an ever-changing ecosystem that evolves each year.
Global , Mar 25, 2024
Press Release
Logicalis elevates global security portfolio with Microsoft verified Managed XDR Partner Status
Logicalis joins an elite group of managed service providers certified to deliver Microsoft’s most advanced managed detection and response services worldwide
Global , Mar 18, 2024
Press Release
Logicalis the first Cisco Global Partner to achieve Sustainable Campus Access Add-On Specialisation
Logicalis receives inaugural specialisation that acknowledges its position at the forefront of sustainable global managed service delivery. The specialisation was awarded to Logicalis for supporting its customers to reduce the carbon footprints of their digital ecosystems
Global , Mar 4, 2024
Press Release
Logicalis 2024 CIO Report: AI and security are top priorities amidst barriers to transformation
Discover the top priorities of tech leaders according to the Logicalis 2024 CIO Report. Learn about AI, digital transformation, and cybersecurity investments amidst economic uncertainty.

Global , Feb 19, 2024
Achieving Secure, Scalable, and Sustainable Networks with Intelligent Connectivity
Enhance your organisation's security posture with Cisco's comprehensive network security solutions. Scale easily and protect your business from evolving threats with our expertise.
Global , Feb 14, 2024
Dina Knight joins QinetiQ board as Non-Executive Director
Dina Knight will join the QinetiQ Board as Non-Executive Director on 1 March 2024. Dina’s NED position will compliment her role as Chief People Officer at Datatec and Logicalis International, accountable for its people operations and strategy.
Global , Feb 12, 2024
Evolving Cloud trends
Cloud technology continues to be at the forefront of innovation and a critical element to any digital strategy in 2024. As businesses increasingly embrace digital transformation, understanding and leveraging, evolving cloud trends and technologies is crucial to staying competitive in the market.
Global , Jan 31, 2024
The remarkable impact of breathwork on wellbeing
The next session in our Revive and Thrive series focuses on the damage done by stress and how we can alleviate not just stress, but also build abilities and skills that support our overall wellbeing.
Global , Jan 9, 2024
Press Release
Logicalis’ latest release of AI-powered digital fabric platform delivers enhanced visibility for CIOs
Logicalis announces the release of the next generation of its Digital Fabric Platform, providing CIOs with deeper-level insights and recommendations to underpin the performance of their entire digital ecosystem.
Global , Dec 11, 2023
Progressing your responsible business journey
Our responsible business agenda has been shaped by understanding who we are as a business, which social and environmental challenges are important to our customers, partners, people and in the regions that we operate in.
Global , Dec 11, 2023
Inclusion starts with me
Investigating making the invisible visible, the first session in our Revive and Thrive series provided an understanding of how we can look after each other's mental health by changing behaviours, from unconscious bias to consciously include people.
Global , Nov 23, 2023
How technology is changing environmental sustainability
The enablement of sustainability strategies through technology and IT, in this instance is what can truly enable business growth and ESG performance, and there are several ways that they tie together.
Global , Nov 15, 2023
The ethical implications of lacking sustainable business practices
A sustainable society is one that lives within the carrying capacity of its natural and social systems, but as the impact of businesses on the environment has increased dramatically, that balance for a sustainable society has tipped.
Global , Nov 3, 2023
Press Release
Logicalis awarded Global Sustainability Partner of the Year at Cisco Partner Summit 2023
This inaugural award recognises Logicalis’ outstanding sustainability performance and success in helping customers reduce the environmental impact of their IT infrastructure across the globe.
Global , Nov 3, 2023
Logicalis named 2023 Cisco Global Enterprise Networking and Meraki Partner of the Year for the second consecutive year
Last week, we proudly received the 2023 Cisco Global Enterprise Networking and Meraki Partner of the Year award during Cisco’s annual Partner Summit. Here are some key Logicalis and Cisco areas we're co-collaborating on to deliver value and open new opportunities to drive momentum around managed services to deliver sustainable outcomes for our customers.
Global , Oct 26, 2023
Logicalis named inaugural 2023 Cisco Global Sustainability Partner of the Year
Here are some key Logicalis and Cisco areas we're co-collaborating on to deliver value and open new opportunities to drive sustainable practices for our customers, environment, and planet.
Global , Oct 26, 2023
The evolution of ESG: from corporate 'nice-to-have' to corporate necessity
Corporate sustainability has become more than a “nice to have”. We are seeing more and more organisations realise the urgency to act not just because of regulatory pressure, but also because they see sustainability as a way to drive business benefits. Environmental and social governance or ESG which considers sustainability policies and ethical practice, is moving out of the shadows and becoming the next big bet in business transformation providing clear shared value.
Global , Oct 18, 2023
Choosing the right MSSP -Top 5 credentials to look for when selecting MSSP
Our recent CIO survey shows over half of respondents plan to increase their risk management investment. They also consider malware and ransomware significant risks that their organisations will face in the coming year. But what should an organisation look for in choosing the right MSSP?
Global , Oct 16, 2023
Forward Faster: Accelerating SDGs and Sustainable Leadership
While we are working hard on our robust responsible business plan, especially with regards to our sustainability goals, there is still a long way for us all to go. Responsible Business Manager Sharon Kekana, recently participated in the UN Global Compact Leaders Summit, held at the Javits Centre in New York.
Global , Oct 16, 2023
In the news, Blog
5G and AI: drivers of reindustrialisation in developed countries
Emerging technologies, such as 5G, IoT and Artificial Intelligence (AI), have the potential to promote profound transformations in the way global industry is organized.
Global , Oct 5, 2023
In the news
Why the CIO is key to driving business sustainability
Sustainability initiatives in the business world, are becoming more of a requirement and technology plays a central role. Read Bob's three steps for CIOs to become leaders in driving their sustainability agendas.
Global , Oct 4, 2023
Sustainable travel – a realistic goal in the IT industry?
Catriona Walkerden, Global VP, Marketing takes us through how the new sustainable travel policy at Logicalis influenced her recent business travel decisions. See how she got on ...
Global , Sep 21, 2023
In the news
What should organisations look for in an SD-WAN as-a-Service provider?
Pedro Morgado outlines the key factors organisations need to consider when selecting an SD-WAN solution provider.
Global , Sep 20, 2023
Logicalis strengthens Global Cisco team with the promotion of Wayne Haylett to Global Cisco Alliance Director
Logicalis announces the promotion of Wayne Haylett from Logicalis Australia to the position of Global Cisco Alliance Director, reporting to Global VP Strategic Alliances, Richard Simmons.
Global , Sep 18, 2023
The role of technology in achieving sustainability goals
Technology has undoubtedly revolutionised the world, however, technology and sustainable approaches are not mutually exclusive. There is a duality to technology and sustainability; while technology itself must be made more sustainable, the way we use technology may be the key to acting more sustainably and tackling the climate crisis.
Global , Sep 4, 2023
The power of next generation connectivity
Business leaders need to create environments that can adapt to maximise opportunities, mitigate risks and most importantly be able to scale both securely and sustainably. The key to this is connectivity.
Global , Sep 4, 2023
Press Release
Logicalis expand their suite of Cisco-powered managed services with the launch of Intelligent Connectivity
Logicalis announce the launch of Intelligent Connectivity powered by Cisco, a suite of solutions including Private 5G, SD-WAN, SASE, SSE, SD-Access and ACI Data Centre and become First Cisco Global Partner to achieve Managed Private 5G strategic designation.
Global , Aug 15, 2023
Logicalis publishes Environmental Statement including benchmarks and commitments
As part of our commitment to sustainability and transparency, we have released our Environmental Statement, which discloses our carbon emission baseline figures and lays out a roadmap for achieving our ambitious carbon reduction goals.
Global , Aug 4, 2023
Logicalis celebrates incredible growth of Microsoft performance
FY23 has been an extraordinary year for Logicalis’s Microsoft partnership. We’ve seen 60% year-on-year growth reflecting our unwavering commitment to helping customers deliver business value through digital transformation.
Global , Jul 14, 2023
Is sustainability becoming the mandatory brand value?
Employees and customers are looking to organisations for proactive sustainability action to help tackle the worsening climate situation. How can marketing help drive the right behaviour in organisations?
Global , Jul 10, 2023
Bringing use cases to life: Logicalis creates customer specific use cases with Private 5G Labs
Integration of use cases as well as presentation and training for new 5G solutions
Global , Jul 10, 2023
Employee burnout: Addressing the root causes and empowering leaders to combat it
Employee burnout has become an increasingly alarming concern in recent years and it's now a necessity for modern businesses to empower leaders to proactively address burnout, creating a workplace that promotes employee well-being and productivity.
Global , Jul 6, 2023
New platform from Logicalis gives CIOs real-time view of environmental impact
Logicalis announces the launch of the Managed Digital Fabric Platform, created to give CIOs a real-time view of how their entire digital ecosystem is performing across key metrics, including environmental impact.
Global , Jun 30, 2023
CIOs come together to address sustainability at the annual Logicalis CIO Summit
CIO commitment needed to measure, manage and reduce carbon emissions Keynote address from Leading Analyst Firm reveals ESG is growing in importance to IT buyers but cautions against investing in tech that doesn’t deliver against goals
Global , Jun 30, 2023
Sustainability now critical to CIOs – and they’re looking to MSPs for help
Sustainability is a key consideration when choosing an IT supplier: nearly half of CIOs consider carbon output energy efficiency when selecting new suppliers.
Global , Jun 30, 2023
In the news
CIOs come together to address sustainability at the annual Logicalis CIO Summit
Keynote address from Leading Analyst Firm reveals ESG is growing in importance to IT buyers but cautions against investing in tech that doesn’t deliver against goals.
Global , Jun 30, 2023
In the news
CIOs increasing spending in ESG performance and metrics
CIOs are increasing investment in technologies that help drive business value and ESG performance and highlighted growing trends such as linking executive pay to ESG metrics, a Logicalis summit was told.
Global , Jun 27, 2023
Logicalis renews accreditation as Cisco Global Gold Integrator
As one of only six Cisco Global Gold Certified Partners, Logicalis successfully delivering innovation, engagement, and value for customers worldwide.
Global , Jun 22, 2023
CIO Summit 2023
Our summit, themed Forging a Digital Path to Sustainable IT, gave CIOs insight and inspiration from experts driving sustainable innovation in their industry and highlighted the vital role of IT as an enabler for sustainable transformation.
Global , Jun 16, 2023
Logicalis awarded Next Generation MSP Innovation award at the European MSP Awards 2023.
We created the Managed Digital Fabric platform to enable our customers to run their IT infrastructure and applications more efficiently, securely, and sustainably. We're thrilled that Logicalis has been awarded the Next Generation MSP Innovation Award at the European MSP Innovation Awards 2023 for this platform.
Global , Jun 2, 2023
Do managed service providers hold the answers to a sustainable future in IT?
With sustainability top of mind for everyone, organisations are demanding transparency and clarity from suppliers and partners around ESG goals today.
Global , May 12, 2023
Introducing our Managed Digital Fabric Platform
In response to the need to support our customers and focus on critical activities that matter, such as optimising resources and reducing costs, in 2022, we developed the Managed Digital Fabric platform. Based on machine learning and AI, The Managed Digital Fabric Platform provides our managed services customers with a real-time view of their digital infrastructure across cloud, security, workplace, and connectivity.
Global , May 9, 2023
Superhuman scale: What's possible with the next generation of digital managed services?
The era of digital managed services is upon us, offering superhuman scale for an organisation’s technology ecosystem. What can you expect from this new generation of digital MSPs? Markus Erb, VP of Services for Logicalis, shares his insights on the possible.
Global , Apr 3, 2023
How CIOs are building resilience with digital managed services
This blog explores how CIOs are building resilience with digital managed services.
Global , Apr 3, 2023
Three ways CIOs are driving the transition to net zero
The transition to net zero offers a great opportunity for CIOs to increase their strategic influence across the business. The Logicalis Global CIO Report 2023 identified three ways CIOs are driving the transition to net zero.
Global , Mar 6, 2023
Press Release
Logicalis take people strategy to new level with appointment of Dina Knight as its first Group Chief People Officer
Logicalis, a global technology service provider, today announces the appointment of Dina Knight to the position of Chief People Officer, in a newly created role within the executive team, reporting to Global CEO, Robert Bailkoski.
Global , Feb 21, 2023
Budget cuts make innovation a top CIO priority according to the Logicalis global CIO report 2023.
While firms are concerned about the global economy and continue to cut budgets, CIOs are responding by taking on more of a strategic role.
Global , Feb 10, 2023
Bold leadership elevates CIOs to the boardroom, according to Logicalis global study
CIOs have stepped into the role of digital evangelist and strategic advisor, according to the 2023 Global CIO Survey from Logicalis, a global technology service provider.
Global , Feb 1, 2023
Driving sustainability as Architects of Change
Being a responsible business is about the ability to make a commitment and make a difference. Charissa Jaganath discusses what Logicalis is doing to make a difference and why driving sustainability is so important to us.
Global , Jan 23, 2023
Logicalis CTO Toby Alcock highlights enterprise tech trends for 2023
Digital innovation, cybersecurity, workplace talent, sustainability, and recession-proofing top the list At Logicalis, as we look forward to yet another busy and challenging year for the IT industry, we've put together the strategic technology trends for 2023 that can help IT leaders see through the current economic and market challenges and deliver sustainable business outcomes that matter.
Global , Dec 21, 2022
How have channel partners made their business more sustainable this year?
How have partners made their businesses more sustainable this year? CRN/Channel Web quizzed six UK and European resellers and distributors bosses, including Logicalis CEO, Bob Bailkoski, on what they have done internally to bolster their environmental commitments
Global , Dec 20, 2022
How can CEOs better incorporate sustainability into their decision-making?
Bob Bailkoski, CEO, shares his top three pieces of advice for CEOs wishing to better incorporate sustainability into their decision making.
Global , Dec 20, 2022
CTO Sessions with IDG Connect: Toby Alcock, CTO Logicalis
Toby speaks to IDG Connect about how he became our CTO, the biggest issues customers are facing currently, how we’re focussed on customer outcomes with automation and how to align technology with business goals.
Global , Dec 19, 2022
Logicalis commits to Corporate Net Zero Standard (SBTi), marking another milestone in its sustainability journey
London, United Kingdom – 19 December 2022: Logicalis, a global technology service provider, today announces its commitment to the Science Based Targets initiative (SBTi) Corporate Net Zero Standard - the world's first framework for corporate net zero target setting in line with climate science.
Global , Dec 12, 2022
Logicalis Group CEO on sustainability: 'There is scope for the channel to work more closely together to achieve greater impact'
Bob Bailkoski, shares with Channel Partner Insight how there is scope for the channel to work more closely together to achieve greater impact
Global , Dec 9, 2022
Logicalis CEO: Sustainability is non-negotiable
Logicalis CEO, Robert Bailkoski talks to Simon Quicke, editor of MicroScope UK, about sustainability and how the business is playing its part in reducing the strain on the planet and how he’s encouraging staff, suppliers and customers to get involved
Global , Nov 22, 2022
How Digital Managed Services are driving business value for CIOs
Today’s CIOs face key challenges around futureproofing, innovating, and the perennial skills shortage. As businesses increasingly adopt a digital-first approach, CIOs need to deliver solutions and services that are future-ready, to mitigate the risks of these challenges.
Global , Nov 16, 2022
Logicalis's Intelligent Connectivity solution now Powered by Cisco
Logicalis's Cisco Powered Intelligent Connectivity delivers SD-WAN and SASE offerings in a managed capacity, providing real-time insights into network performance. Find out more.
Global , Nov 14, 2022
We’re an Uber workforce now
Post pandemic, businesses no longer have centralised workforces. What does this mean for operations and management? Our very own Group Senior Vice President of Human Resources, Justin Kearney, shares with UNLEASH how “organisations are turning to technology to create a truly collaborative hybrid workplace and manage the younger generations satisfactorily.”
Global , Nov 7, 2022
Logicalis Recognised as Winner of the Cisco Global Enterprise Networking and Meraki Partner of the Year Award at Cisco Partner Summit 2022
We’re delighted Cisco recognises Logicalis as the Global Enterprise Networking and Meraki Partner of the Year 2022. These awards are a consequence of the 25-year strategic partnership between Logicalis and Cisco, uniting to drive customer success. Congratulations to everyone involved
Global , Oct 27, 2022
Will business air travel ever return to its pre-Covid heights?
While the aviation sector is slowly taking off again, it is struggling to attract passengers who have realised how much work can be done virtually. Bob Bailkoski, CEO Logicalis joins the debate with Raconteur, sharing his views on sustainable travel.
Global , Oct 11, 2022
Confessions of a CEO: In a climate conscious world, does the train beat the plane?
More and more climate-conscious travellers are opting to take the train instead of flying. With this in mind, and a business meeting coming up in Cologne, Bob decided to take the 580km trip by train. Here's how he got on
Global , Sep 28, 2022
Logicalis welcomes the overhaul of the Microsoft partner eco-system
Read how Logicalis has worked really hard, not only to be aligned with Microsoft Cloud, but also with Microsoft’s focus sectors. We have deep expertise in retail, health and financial services, and can leverage the full potential of Microsoft Cloud in every sector.
Global , Sep 16, 2022
Cilnet changes its name to Logicalis Portugal
Cilnet a Logicalis Company, announces its name change to Logicalis Portugal. This brand evolution was planned and carried out according to a previously defined strategy, with Logicalis being the identity that represents the company’s current range of services and offers.
, Sep 16, 2022
Logicalis Portugal becomes the first Iberian partner to achieve a Citrix Platinum Plus certification
June 25, 2021 – Logicalis Portugal, a global IT solutions provider, has just achieved the Citrix Platinum Plus certification, becoming Citrix's first Iberian partner with this level of certification.
Global , Sep 16, 2022
Logicalis Group announces new regional structure, merging Channel Islands, Ireland, and United Kingdom
Logicalis, an international IT solutions and managed services provider, today announces a new regional structure, bringing together three geographies (Channel Islands, Ireland, and the United Kingdom) to form a single business unit.
Global , Jul 9, 2022
Strong digital foundations are the key to enterprise agility
Safeguard your employees and data with a secure IT foundation. Learn how managed cloud services can protect staff, productivity, and morale in today's hybrid and remote work environment.
Global , Jun 16, 2022
Do CIOs hold the key to unlocking sustainable innovation?
Businesses need robust plans to lower emissions and reduce their impact on the environment. Businesses not only require sustainable innovation but efficient innovation through taking a data-driven approach and managing IT to outcomes, not uptime.
Global , May 11, 2022
Secrets from future facing CISOs for long-term success
Discover strategies for maintaining security and driving innovation in the modern marketplace. Learn how to balance risk and ensure long-term success in data security and risk management.
Global , Apr 25, 2022
Logicalis target digital-first leaders with launch of managed Intelligent Connectivity service
London, United Kingdom – 25th April 2022: Logicalis, a global IT solutions and managed service provider, today announces the launch of Intelligent Connectivity, a solution designed to empower digital-first customers to improve business performance and user experience by operating with connectivity as a managed service.
Global , Apr 21, 2022
Rethink connectivity to create productivity and scalability
Discover how businesses can optimise processes, reduce costs, and deliver new products at scale through the power of IoT connectivity.
Global , Apr 19, 2022
Logicalis reflect on three-year journey of innovation and growth with Microsoft
Discover how Logicalis partners with Microsoft to provide the best hybrid cloud solutions and managed services. Learn about our advanced specialisations and industry-leading solutions.
Global , Mar 31, 2022
Allow employees to collaborate freely
Boost productivity and foster effective communication with employee collaboration tools. Find out how to support your dispersed workforce and drive business success.
Global , Mar 24, 2022
CIO priorities: Business continuity, resilience and mitigating risk
With the right strategic approach, companies can combine security, resilience, and innovation, to create a clear competitive advantage, but businesses must act now to capitalise on the tools and skills available to them
Global , Mar 22, 2022
A new generation of workers demand a new approach to the workplace
The rise of remote working and a younger digitally native workforce, is shaking up traditional business structures. Many organisations are still adapting their workspaces to cope and in some instances need to overhaul their approach to work entirely.
Global , Mar 21, 2022
Only a third of CIO's cite cyber-risk mitigation as a performance measure
London, 21 March 2022: While 94% of CIOs acknowledged some form of serious threat over the next 12 months, only 27% listed business continuity and resilience as a top-three priority during the next 12 months and barely a third cited risk mitigation as a measure of performance. These findings come from the fourth section of the 2021 Global CIO Survey from Logicalis, a global provider of IT solutions.
Global , Mar 15, 2022
Diversity as a key differentiator in transformation
Discover how embracing equality, diversity, and inclusion can drive business success. Learn why diverse and inclusive workplaces are essential in today's competitive landscape.
Global , Mar 14, 2022
Logicalis appoints Damian Skendrovic as EMEA CEO
London, 14th March 2022: Logicalis, an international IT solutions and managed service provider, is pleased to announce the appointment of Damian Skendrovic to the role of CEO for the EMEA region, as of 8th March 2022.
Global , Mar 9, 2022
Actionable insights are the missing link to collaboration in the hybrid workplace
Discover how to overcome barriers in the hybrid workplace and promote collaboration for increased innovation. Learn how data and insights can drive better employee communication and results
Global , Feb 16, 2022
Rethink the modern workspace to empower employees
Discover how senior leaders can create a balance between business needs and employee preferences to cultivate a productive hybrid office environment.
Global , Feb 9, 2022
Is effective collaboration no longer bound by time or place?
Discover how to empower your employees and optimize collaboration in the digital workplace for enhanced productivity and success.
Global , Feb 1, 2022
Business trend predictions for 2022
Logicalis Group CEO Bob Bailkoski, sat down with us and talked us through his top three predictions for the year ahead. Find out what they are ...
Global , Jan 26, 2022
CIOs spending more time on innovation than ever before
CIOs are spending more time on innovation, with three quarters stating they have increased innovation efforts, according to the 2021 Global CIO Survey from Logicalis
Global , Jan 26, 2022
Creating a culture of innovation and the digital workplace
Alongside the innovation within company culture, CIOs must ensure their employees are satisfied as the hybrid workplace takes shape.
Global , Jan 13, 2022
Bringing together an intergenerational workforce for the future
To attract and retain talent, leaders need to take the time to understand what younger generations really want from their work environment and consider how to empower an increasingly divided intergenerational workforce.
Global , Jan 11, 2022
Logicalis take the digital workplace ‘beyond productivity’ with the launch of collaboration suite
Logicalis, a global IT solutions and managed service provider, today announces the launch of their digital workplace solution designed to help organisations manage, measure and scale the collaboration experience for the digital workplace.
Global , Dec 7, 2021
Rethinking the way we work
Logicalis helps businesses rethink their approach to digital transformation strategy to take a hybrid approach with agility, scalability, and innovation at the core, building resilient businesses for the future.
, Nov 30, 2021
75% of surveyed CIOs struggle to unlock data insights within their organisation
While 78% of businesses realise the value of digital transformation, only a quarter are using data to drive business strategy
Global , Nov 29, 2021
Unlocking data to drive business strategy and accelerate growth
The need for digital transformation is more prevalent than ever with the pandemic triggering companies to shift and realign their priorities. Results from this year’s survey identified that three quarters of respondents admit their organisations are wrestling with their abilities to unlock data
Global , Nov 16, 2021
Logicalis recognised with 18 awards at the Cisco Partner Summit 2021
One of only five Cisco Global Gold Certified Partners, Logicalis has worked in partnership with Cisco for over 25 years to combine global expertise with intelligent cutting-edge solutions that deliver business success through digital transformation
Global , Oct 18, 2021
Logicalis reshape the traditional approach to Enterprise Security with the global launch of Secure OnMesh
Logicalis, a global IT solutions and managed service provider, today announces the launch of its new security solution - Secure OnMesh.
Global , Oct 8, 2021
Logicalis Named EMEA Hybrid Cloud Partner of the Year at NetApp EMEA & LATAM Partner Awards 2021
Logicalis, an international IT solutions and managed services provider, has just won the NetApp Partner Award for EMEA Hybrid Cloud partner of the Year. NetApp, a global cloud-led, data-centric software company, presents these accolades annually in recognition of the investment and cooperation of its key partners.
, Oct 4, 2021
Logicalis joins Microsoft Intelligent Security Association (MISA)
Monday 4th October 2021, London – Logicalis, an international IT solutions and managed service provider, has joined the Microsoft Intelligent Security Association (MISA). MISA is an ecosystem of independent software vendors and managed security service providers that have integrated their security solutions to better defend against a world of increasing threats. MISA members are experts from across the cybersecurity industry with the shared goal of improving customer security. Each new member brings valuable expertise, making the association more effective as it expands.
Global , Sep 28, 2021
The Changing Role of the CIO - Emerging Agents of Change
Strong customer relationships have become a critical business priority according to the results of the first report in a four-part series following the eighth annual Logicalis Global CIO Survey.
Global , Sep 21, 2021
Want return on digital investments? Look to a managed service provider
Today every business, regardless of industry, is operating in a hyper-competitive environment with everyone battling for their place in the digital economy
Global , Sep 14, 2021
The holy trinity in effective digital workplaces? Cloud, data, and security
Discover the key elements of a successful digital workplace strategy and how enlisting the help of an expert partner can ensure continued success. Unlock the full potential of your organisation with a holistic approach to digital workplace strategy.
Global , Sep 7, 2021
Can a lifecycle approach to cloud adoption improve success?
Cloud migration offers a range of benefits from security to scalability. Successful and optimised cloud migration, especially in the post-pandemic digital economy, will be critical for achieving real-time performance and efficiency.
Global , Aug 31, 2021
Truly successful digital transformation includes employee experience from the start
Discover how a human-centric approach to digital transformation can enable business growth and optimize employee performance. Learn how to tackle the challenges and empower your workforce with the right digital tools.
Global , Aug 26, 2021
The connected workplace is not just for offices
Discover how WiFi 6 and 5G are revolutionizing industries. Together Cisco and Logicalis bring unrivaled expertise to personalize IoT and 5G solutions for your business.
Global , Aug 24, 2021
5G: The next enterprise revolution
5G is less about high-speed connectivity and more about unleashing data and computing capability. With the ability to power future solutions such as autonomous cars, 5G technology can accelerate the growth of low-cost enabled Internet of Things (IoT) devices and more
Global , Aug 12, 2021
Logicalis recognised as a Leader in the IDC MarketScape on Worldwide Network Consulting Services 2021 Vendor Assessment
Logicalis announced today that it has been named a Leader in the IDC MarketScape: Worldwide Network Consulting Services 2021 Vendor Assessment (Doc #US48076121, August 2021).
Global , Aug 10, 2021
Will digital transformation help you compete in the digital economy?
Discover the power of digital transformation in driving business growth, efficiency, and customer satisfaction. Unlock new possibilities and create a digital-first organization with data at its core
Global , Jul 28, 2021
Logicalis recognised as global finalist of 2021 Microsoft Solutions Assessment Partner of the Year
London, Wednesday 28th July 2021 — Logicalis, an international IT solutions and managed service provider, today announced it has been named a global finalist of Solutions Assessment 2021 Microsoft Partner of the Year Award. The company was honoured among a global field of top Microsoft partners for demonstrating excellence in innovation and implementation of customer solutions based on Microsoft technology.
Global , Jul 5, 2021
Enabling collaboration in a digital workplace
It’s pretty clear that digital workplaces are here to stay in one form or another. As a growing number of organisations move to make flexible or remote working part of their permanent policy, there are clear benefits to a digital workplace.
Global , Jun 28, 2021
Preparing for the hybrid workforce of the future
Discover how a collaborative workplace can enhance communication, build company culture, and improve market responsiveness. Partner with experts for the right collaboration tools.
Global , Jun 15, 2021
How the global chip shortage is driving data centre projects to the cloud
Explore how moving to the cloud can offer a cost-effective and flexible solution for managing new projects and workloads during the chip shortage. Learn how cloud managed services can provide ample capacity without the high costs of an on-premises solution.
, May 19, 2021
Logicalis Selected as Oracle Cloud Partner of Choice for European OCRE Tender
London – 19, May 2021 – Logicalis Group, an international IT solutions and managed services provider, and a member of Oracle PartnerNetwork (OPN) today announced it has been chosen as the Oracle Cloud Partner of Choice for the Open Clouds for Research Environments (OCRE) framework across Germany and Ireland.
, May 12, 2021
Logicalis Group Strengthens Position as Leading Digital Transformation Enabler with the Appointment of Toby Alcock to Chief Technology Officer
LONDON. 12, May 2021: Logicalis, an international IT solutions and managed service provider, today announces the appointment of Toby Alcock from his current role as Chief Technology Officer, Logicalis Australia, to the position of Chief Technology Officer for Logicalis Group. Alcock’s appointment comes after a strong year of growth for Logicalis.
Global , Apr 29, 2021
Markus Erb joins Logicalis as the new Group VP of Services to drive global alignment in Managed Services
April 29th, 2021 – Logicalis, an international IT solutions and managed services provider, today announces the appointment of Markus Erb to the position of Group VP for Services, a role created to drive alignment and innovation within the newly established Global Services Organisation (GSO) within Logicalis.
Global , Apr 28, 2021
Your business may not exist if you are not in the Cloud
Discover how transitioning to the cloud can help your business adapt to changing customer demands and achieve greater agility. Explore the benefits of cloud technology and gain a competitive edge
Global , Apr 22, 2021
Logicalis appoints Catriona Walkerden, Vice President for Global Marketing, to drive transformation agenda
April 22nd, 2021 – Logicalis, a leading international IT solutions and managed service provider, today announces that Catriona Walkerden is making the transition from her current role as National Marketing Lead of Logicalis Australia to VP, Global Marketing for Logicalis Group.
Global , Apr 5, 2021
Big Data and Cloud: The perfect business partners
Discover how cloud technology and infrastructure advancements enable businesses to unlock the true value of Big Data analysis. Learn how flexible infrastructure and scalable services support variable workloads.
Global , Mar 30, 2021
Run VMware on Azure? Yep, you read it right!
Azure VMware Solution shouldn’t be overlooked as a valid step on a cloud journey. It enables migration to the cloud at an infrastructure level, without disrupting application or operations teams.
Global , Mar 26, 2021
How the pandemic uncovered the need for global solutions with local execution
Successful digital transformation requires the integration of technology into all areas of a business. The aim is to fundamentally change how an organisation operates and delivers for its customers.